Codebase Memory: The 14 Best Tools for AI Coding Agents (2026)
Comparison · · Published October 2026 · 13 min read
By Ashwin Gopinath, CEO
Disclosure: Sentra makes one of the products compared here. We checked each vendor's own documentation and pricing, link every source, and name the better choice when it is not Sentra.
TL;DR
- The best codebase memory tools for AI coding agents in 2026 are Sentra, Augment Code, claude-mem, codebase-memory-mcp, GitNexus, CodeGraph, Aider, Cognee, CoreStory, projectmem, CodeAlive, Sourcegraph Cody, Repomix and Repowise. They split into two groups: local code graphs that index one machine's repositories, and shared memory layers that every engineer and agent reads.
- Local graphs and session memory (claude-mem, codebase-memory-mcp, GitNexus, CodeGraph) are free, fast and private. They answer "what calls this function". They do not answer "why is it built this way" or "what did the team decide last month", because that lives in Slack, Jira and pull request threads.
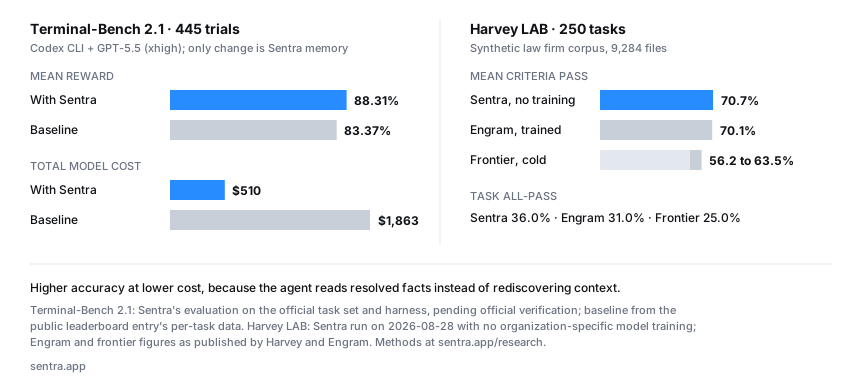
- The questions that separate tools are shared indexing across agents, how the memory updates after code changes, and cost per completed task. Most vendors publish token savings on lookups. Sentra publishes cost on completed tasks: on Terminal-Bench 2.1, a coding agent with Sentra scored 88.31% mean reward against 83.37% without it across 445 trials, at 72.6% lower model cost and 41.2% fewer tokens.
- Our pick for teams is Sentra, the shared layer: one org-wide graph, built from GitHub, Slack, Jira, meetings and docs, that every agent reads over MCP and REST. Teams keep a local code graph for symbol lookups and use Sentra for decisions, conventions and what changed.
Best by use case
- A team whose agents need decisions, conventions and history from GitHub, Slack, Jira and meetings: Sentra.
- Memory across Claude Code sessions on one machine, free: claude-mem.
- A local code graph over MCP for symbol and call lookups: codebase-memory-mcp, GitNexus or CodeGraph.
- An IDE agent with its own context engine for large codebases: Augment Code.
- Pair programming in the terminal with a repository map: Aider.
- Packing a repository into one prompt: Repomix.
What is codebase memory?
Codebase memory is a persistent store of what an AI coding agent has learned about a codebase, so the agent stops re-reading files and re-deriving structure on every task. The simplest form is a local index of symbols and call graphs; the fuller form also holds decisions, conventions and the history of what changed and why, shared across every agent and engineer.
The cost of not having it is easy to measure. One developer reported his agent burning $40 in tokens before he noticed it was re-reading the same imports on every query. The same post documents a ProcessOrder call trace costing 45,000 tokens by file crawling and 200 tokens through a graph query, and persistent indexing across 372 real questions averaged 121x token savings.
Real codebases never hold still. A static index answers fast until a refactor lands, then confidently serves a pattern that no longer exists. Knowing when code stopped being true is the harder problem.
How to evaluate a codebase memory tool
These six tests separate the field quickly.
- Shared indexing across agents. Ask a second agent, on a second machine, something the first one learned. Local graphs live under one user's cache directory; a shared layer answers the same way for everyone.
- Updates after code changes. Merge a rename, then query it. Look for a file watcher, a commit hook or a push-triggered reindex, and check whether the old pattern is marked superseded or simply overwritten.
- Cross-repository and cross-tool reach. Ask about a decision made in a different repo, or in a Jira ticket. Most answers to "why" live outside the code.
- Staleness handling. Change a convention, then ask about it a week later. A tool with no time model serves the old answer with full confidence.
- Cost per completed task. Measure model spend per task that passes, not tokens per lookup. A tool that saves tokens on exploration but lowers the pass rate costs more.
- Governance. Ask who can see what the tool remembers. Permissions matter the moment memory holds anything beyond public code.
The mid-2026 wave: GitNexus, codebase-memory-mcp and CodeGraph
Three open-source code graphs arrived in mid-2026 and now draw most of the search interest. All three are local, all three speak MCP, and they differ in license, update model and how much they expose. Our side-by-side comparison of GitNexus, codebase-memory-mcp and CodeGraph goes deeper on each.
| codebase-memory-mcp | GitNexus | CodeGraph | |
|---|---|---|---|
| GitHub stars (Oct 2026) | About 47,500 | About 48,000 | About 75,000 |
| License | MIT | PolyForm Noncommercial | MIT |
| MCP tools | 17 | 6 | 1 by default, 7 more opt-in |
| Updates after changes | Background watcher, incremental | analyze --watch; auto-reindex is enterprise | OS file watcher, 2 second debounce |
| Sharing | Commit a compressed graph snapshot | One HTTP MCP server per machine | Daemon shared across sessions on one machine |
- codebase-memory-mcp indexes code, docs and infrastructure files into a persistent local graph, vendors 162 tree-sitter grammars, and keeps the index under
~/.cache(github.com). - GitNexus indexes symbols, calls and execution flows, with a CLI, MCP tools and a web explorer that reads the local index. Its unified cross-repository graph and auto-reindexing are listed as enterprise features, and the PolyForm Noncommercial license means commercial use needs a separate license (github.com).
- CodeGraph stores symbols and edges in local SQLite with full-text search and resyncs on file events (github.com). Several unrelated projects share the name, so check the repository before you install.
All three remove re-derivation for one developer. None provides shared, governed, organization-level memory, the axis the rest of this page ranks, so they compose with a shared layer rather than replace it.
The 14 best codebase context memory tools, by use case
Sentra
Sentra is organization memory applied to code. It connects GitHub alongside Slack, Jira, Linear, meetings and documents, and resolves what each source says into facts at write time, before storage, rather than guessing at structure when an agent queries. Vector search returns what is close, not what is correct. Sentra stores what is correct, with its source.
Sentra is not the best fit for a solo developer who wants free memory on one machine. claude-mem or a local code graph does that with no setup. Sentra earns its place when several engineers and agents need the same answers, including the reasons behind the code.
Every fact carries when it became true and when it stopped being true. When a pull request replaces a pattern, the old fact gets an end time instead of being deleted, so an agent sees the current convention and can still ask what it replaced. Sentra flags contradictions and stale facts, such as a README that still describes an API the code removed. One org-wide graph serves every person and every agent over MCP and REST, so Claude Code, Cursor, Codex and internal agents read the same answer.
Answers respect each source's existing permissions, so an agent never sees a private repository or channel its user cannot open. Sentra holds SOC 2 Type II and ISO 27001 and runs in the cloud, an isolated VPC or air-gapped on-prem.
Best for
teams running several coding agents across many repositories, where the answer to "why" lives in Slack and Jira and where model spend has become a budget line.Augment Code
Augment's Context Engine keeps a live semantic index of a codebase and its history across repos and services (augmentcode.com). It is now available as an MCP server for Claude Code, Cursor, Zed and other MCP agents; the local indexer reflects local edits immediately, and Context Connectors re-index on every push across GitHub, GitLab and Bitbucket (augmentcode.com). Augment reports 33% lower spend than Claude Code on Terminal Bench 2.0 at effectively the same solve rate (augmentcode.com). It indexes what exists now and does not record when a pattern stopped being valid.
Best for
enterprise teams that want high-quality query-time code retrieval across a large repository estate.claude-mem
claude-mem is the most-starred memory project for coding agents, with about 105,000 GitHub stars under Apache 2.0 (github.com). It hooks into Claude Code and other agents, captures what the agent does during a session, compresses it into semantic summaries and feeds the relevant ones into the next session, with search tools and layered retrieval that shows the token cost of what it loads. Memory belongs to one developer's sessions on one project. It does not read Slack, Jira or pull request threads, so it remembers what your agent saw rather than what the team decided.
Best for
individual developers who want Claude Code to stop rediscovering the same project every session.codebase-memory-mcp
A high-performance local MCP server written in C, with about 47,800 GitHub stars under MIT, described in the wave section above. Its authors report 10x lower token use and 2.1x fewer tool calls than file-by-file exploration in a 31-repository preprint, and note the result depends on workload (github.com).
Best for
individual developers who want the fastest local structural index with zero hosted services.GitNexus
A code knowledge graph with impact analysis and Git diff review tools, with about 48,100 GitHub stars (github.com). Strong for a single developer exploring an unfamiliar repository; check the license before commercial use.
Best for
exploring and refactoring one repository with impact checks before you change it.CodeGraph
A local symbol and call graph that resyncs on file events. CodeGraph reports 62% fewer tokens and 44% lower cost across seven open-source repositories with Claude Opus 4.8 in headless runs (github.com).
Best for
developers who want a lightweight, always-fresh graph with one MCP tool to learn.Aider
Aider is an open-source AI pair programmer for the terminal, with about 49,800 GitHub stars under Apache 2.0 (github.com). It builds a map of the whole repository, the key classes and functions with their signatures, and sends the parts relevant to each request so the model sees structure without reading every file (aider.chat). The map is rebuilt from the code each session, so nothing about past decisions carries over.
Best for
developers who want a git-aware coding agent in the terminal with structural context built in.Cognee
Cognee is an Apache 2.0 memory engine that turns documents, code and conversations into a self-hosted knowledge graph, with code parsed into symbols and dependencies and an MCP server for Cursor, Cline and Claude Code (github.com). Cognee says re-runs process only new or changed files and recommends re-ingesting on each merged pull request, with a separate namespace per service (cognee.ai). See Sentra vs Cognee for the organization-level comparison.
Best for
teams that want to self-host and shape a graph memory themselves.CoreStory
CoreStory builds a persistent specification layer from code: overviews, data models, API specs and integration points, which Claude Code, Codex, Devin, Copilot and Cursor query over MCP or API (corestory.ai). Its focus is understanding legacy systems before modernizing them.
Best for
legacy modernization programs that need readable specs of old code.projectmem
projectmem is an MIT, local-first log of issues, attempts, fixes and decisions, kept in a .projectmem/ folder with git hooks and 17 MCP tools (github.com). A pre-action check warns an agent before it repeats a fix that already failed. Distilled summaries are committed, so teammates share them through git.
Best for
small teams that want a lightweight record of what was tried and why, inside the repo.CodeAlive
CodeAlive combines semantic search, grep and graph traversal with file and line citations, refreshes on every push, and connects GitHub, GitLab, Bitbucket, Azure DevOps and Gitea (codealive.ai). Its RepoQA run cut tokens from 3,996,672 to 2,171,103 and raised answer quality from 70.8% to 77.3%. Plans run from free to Team at $100 a month.
Best for
multi-service teams that need relationship-aware context across Git providers.Sourcegraph Cody
Cody reads repositories through Sourcegraph's code graph and is strong at large-organization code search. Sourcegraph ended Cody Free and Pro on July 23, 2025, and Cody is now sold only with Enterprise (sourcegraph.com). It is code intelligence rather than agent memory.
Best for
existing Sourcegraph Enterprise customers who need code search and navigation.Repomix
Repomix packs a repository into one AI-friendly file with npx repomix@latest, has about 29,000 stars, and can run as an MCP server; its experimental Tree-sitter compression strips implementation detail (github.com). Each run is a fresh snapshot with nothing carried between sessions.
Best for
one-shot reviews and refactor plans on a small or stable repository.Repowise
Repowise indexes once and updates incrementally on every commit, exposes ten MCP tools by default, parses 28 languages to an AST, and scores file health for defect risk and maintainability (github.com). It reports agents opening 3.0 files instead of 7.2 per task. It is AGPL-3.0.
Best for
teams that want commit-fresh indexing plus code-health signals.Comparison at a glance
| Tool | Shared across agents and engineers | Updates after code changes | Context beyond code | Time model |
|---|---|---|---|---|
| Sentra | One org-wide graph, all agents and people | Changes resolved at write time, superseded facts end-dated | Slack, Jira, Linear, meetings, docs, 200+ integrations | When a fact became true and stopped |
| Augment Code | Team index via Context Connectors | Local edits immediately, re-index on push | Commit history, issues, docs | Current state |
| claude-mem | Per developer, per project | Captured during each agent session | What the agent did in past sessions | Session history |
| codebase-memory-mcp | Per machine, snapshot via git | Background watcher | Docs, infra files | Current state |
| GitNexus | Per machine; unified graph is enterprise | analyze --watch | Code only | Current state |
| CodeGraph | Per machine | File watcher | Code only | Current state |
| Aider | Per session | Repository map rebuilt each session | Code only | None |
| Cognee | Self-hosted, per namespace | Re-ingest changed files | Documents, conversations | Not published |
| CoreStory | Platform, shared specs | Continuous ingestion | Generated specs | Not published |
| projectmem | Through committed git files | Git hooks and watcher | Logged decisions and fixes | Append-only event log |
| CodeAlive | Hosted, per workspace | Every push | Code only | Current state |
| Sourcegraph Cody | Enterprise instance | Indexed by Sourcegraph | Code only | Current state |
| Repomix | None | Manual re-run | Code only | None |
| Repowise | Per index | Every commit | Git history | Current state |
Shared indexing, updates and cost per completed task
These are the three questions buyers and evaluators ask most, and the ones list pages answer least.
Shared indexing across agents
A local graph lives in one cache directory. Two engineers index the same repository twice, and an agent on a CI runner starts from nothing. codebase-memory-mcp lets a team commit a compressed snapshot, and its own docs warn this can bloat git history. GitNexus and Augment offer team-level indexes in their enterprise tiers. Sentra holds one graph for the organization, and every agent reads it over MCP or REST with the permissions of the person it acts for. When one agent learns that a module was split, the next agent, in any tool, gets the same answer. For the wider pattern, see how to give coding agents codebase memory.
Updates after code changes
There are three update models. File watchers (codebase-memory-mcp, CodeGraph) keep one machine's index fresh within seconds. Push or commit hooks (Augment, CodeAlive, Repowise) keep a shared index at the latest commit. Both overwrite: after the update, the old pattern is gone and nothing says it was replaced. Sentra adds the time model: a superseded fact is end-dated rather than deleted, so an agent can tell the current convention from the one it replaced, and a contradiction between code and docs is flagged rather than served. The bi-temporal knowledge graph explainer covers the mechanism.
Cost per completed task
Most published numbers measure tokens per lookup on a fixed set of questions. That is a useful signal and a different thing from cost per task that passes. Three vendors publish cost on completed tasks:
| Tool | Benchmark and scope | Result |
|---|---|---|
| Sentra | Terminal-Bench 2.1, a frontier coding agent, 89 tasks, 445 trials, memory as the only change | 88.31% mean reward vs 83.37%; 72.6% lower model cost; 41.2% fewer tokens |
| CodeGraph | Seven open-source repositories, Claude Opus 4.8, headless | 44% lower cost |
| Augment Code | Terminal Bench 2.0, Opus 4.7, against Claude Code | 33% lower spend at the same solve rate |
In dollars, the Sentra run cost $510.30 in total model spend against $1,862.98 for the same agent without memory, using 663.5M tokens. That is $1.15 per trial against $4.19, or about $1.30 per passed trial against $5.02. Higher pass rate and lower spend move in the same direction because the agent reads resolved facts instead of crawling files. For more ways to cut spend, see the best tools to reduce LLM token costs.
Where Sentra fits
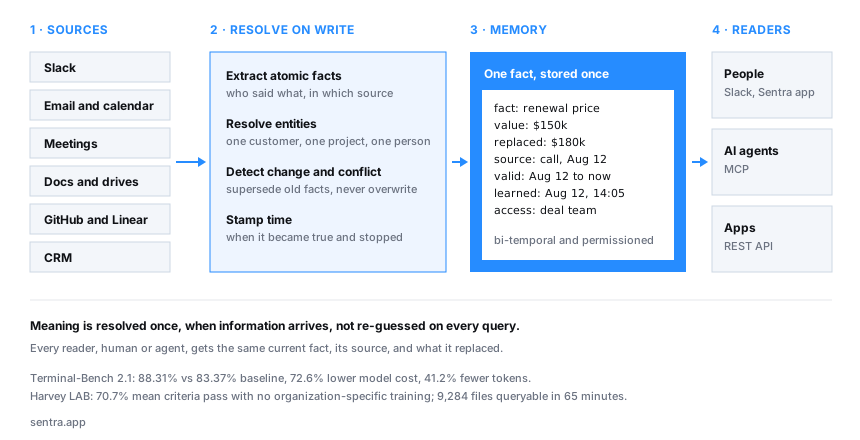
Sentra does not replace your coding agent or your local code graph. It sits under them as the memory they all check with. Cursor, Claude Code and Codex keep doing the work; a local graph keeps answering symbol lookups; Sentra supplies what neither can see: the decision in last week's design review, the Jira ticket that explains a workaround, the convention that changed in March and the one it replaced.
Setup for a coding agent is one command. Sentra runs a remote MCP server, so Claude Code connects over HTTP and signs in through the browser:
claude mcp add --transport http sentra https://api.sentra.app/mcp/Run /mcp once to authorize, then ask something only the company's memory would know, such as what was decided about a recent project. If the answer cites a meeting or a thread, the connection is live. The same server works in Cursor and other MCP clients; the guide to connecting Claude to organizational memory over MCP covers each client and the admin rollout.
Book a demo at /demo to see Sentra answer from your own repositories and threads.
How to choose
Match the tool to the failure you face. If several agents and engineers keep relearning the same decisions, or agents suggest patterns the team retired, you need a shared layer with a time model: Sentra. If you need enterprise retrieval across a large code estate, Augment Code fits. If one developer wants the fastest free local graph, pick codebase-memory-mcp or CodeGraph, and GitNexus for one-repo exploration after a license check. Cognee suits self-hosters, CoreStory suits legacy modernization, and Repomix covers one-shot packing.
Many teams run two: a local graph per developer and Sentra as the shared layer. For memory patterns in practice, see persistent memory for coding agents.
How we evaluated these tools
We scored each tool on shared reach, update model, context beyond code, time model, governance and published cost results. Stars, licenses, tool counts and benchmarks come from each project's own repository or site, checked on 26 October 2026.
FAQ
What is the best codebase memory tool for AI coding agents?
For teams running several agents across many repositories, Sentra, because one org-wide graph holds code decisions, conventions and their history for every agent over MCP and REST. For one developer on one machine, codebase-memory-mcp and CodeGraph are the strongest free local graphs.
What is the difference between codebase-memory-mcp and CodeGraph?
Both are MIT-licensed local code graphs with MCP servers and file watchers. codebase-memory-mcp is written in C, exposes 17 tools and also indexes docs and infrastructure files. CodeGraph stores symbols in SQLite and exposes one tool by default. Neither is shared across machines.
Can multiple AI agents share the same codebase memory?
With local graphs, only on the same machine or through a committed snapshot. A shared memory layer such as Sentra serves one graph to every agent over MCP and REST, with each source's permissions applied to the person the agent acts for.
How does codebase memory stay current after code changes?
Local tools use file watchers; hosted tools re-index on push or commit. Those keep the index current but overwrite the old state. Sentra also end-dates superseded facts, so an agent can tell the current pattern from the one it replaced.
How do I give an agent codebase context across GitHub, Slack and Jira?
Use a memory layer that connects all three. Sentra connects GitHub, Slack, Jira and more than 200 other tools, resolves them into facts with sources, and serves them to the agent over MCP.
Does codebase memory reduce cost per task?
It can. On Terminal-Bench 2.1, a coding agent with Sentra scored 88.31% mean reward against 83.37% without it across 445 trials, at 72.6% lower model cost and 41.2% fewer tokens.
What does bi-temporal awareness mean in plain terms?
Every fact carries when it became true and when it stopped being true. An old pattern is end-dated instead of deleted, so an agent knows it was valid last quarter and does not apply it today.